The test
FinanceBench, by Patronus AI, asks 150 analyst questions about US public companies: figures, ratios and judgements. The answers sit in 84 annual, quarterly and current reports (10-K, 10-Q, 8-K), and each question names its document. It is one of the tests in our benchmark report, version 3.1, of 20 October 2026.
How to read the numbers
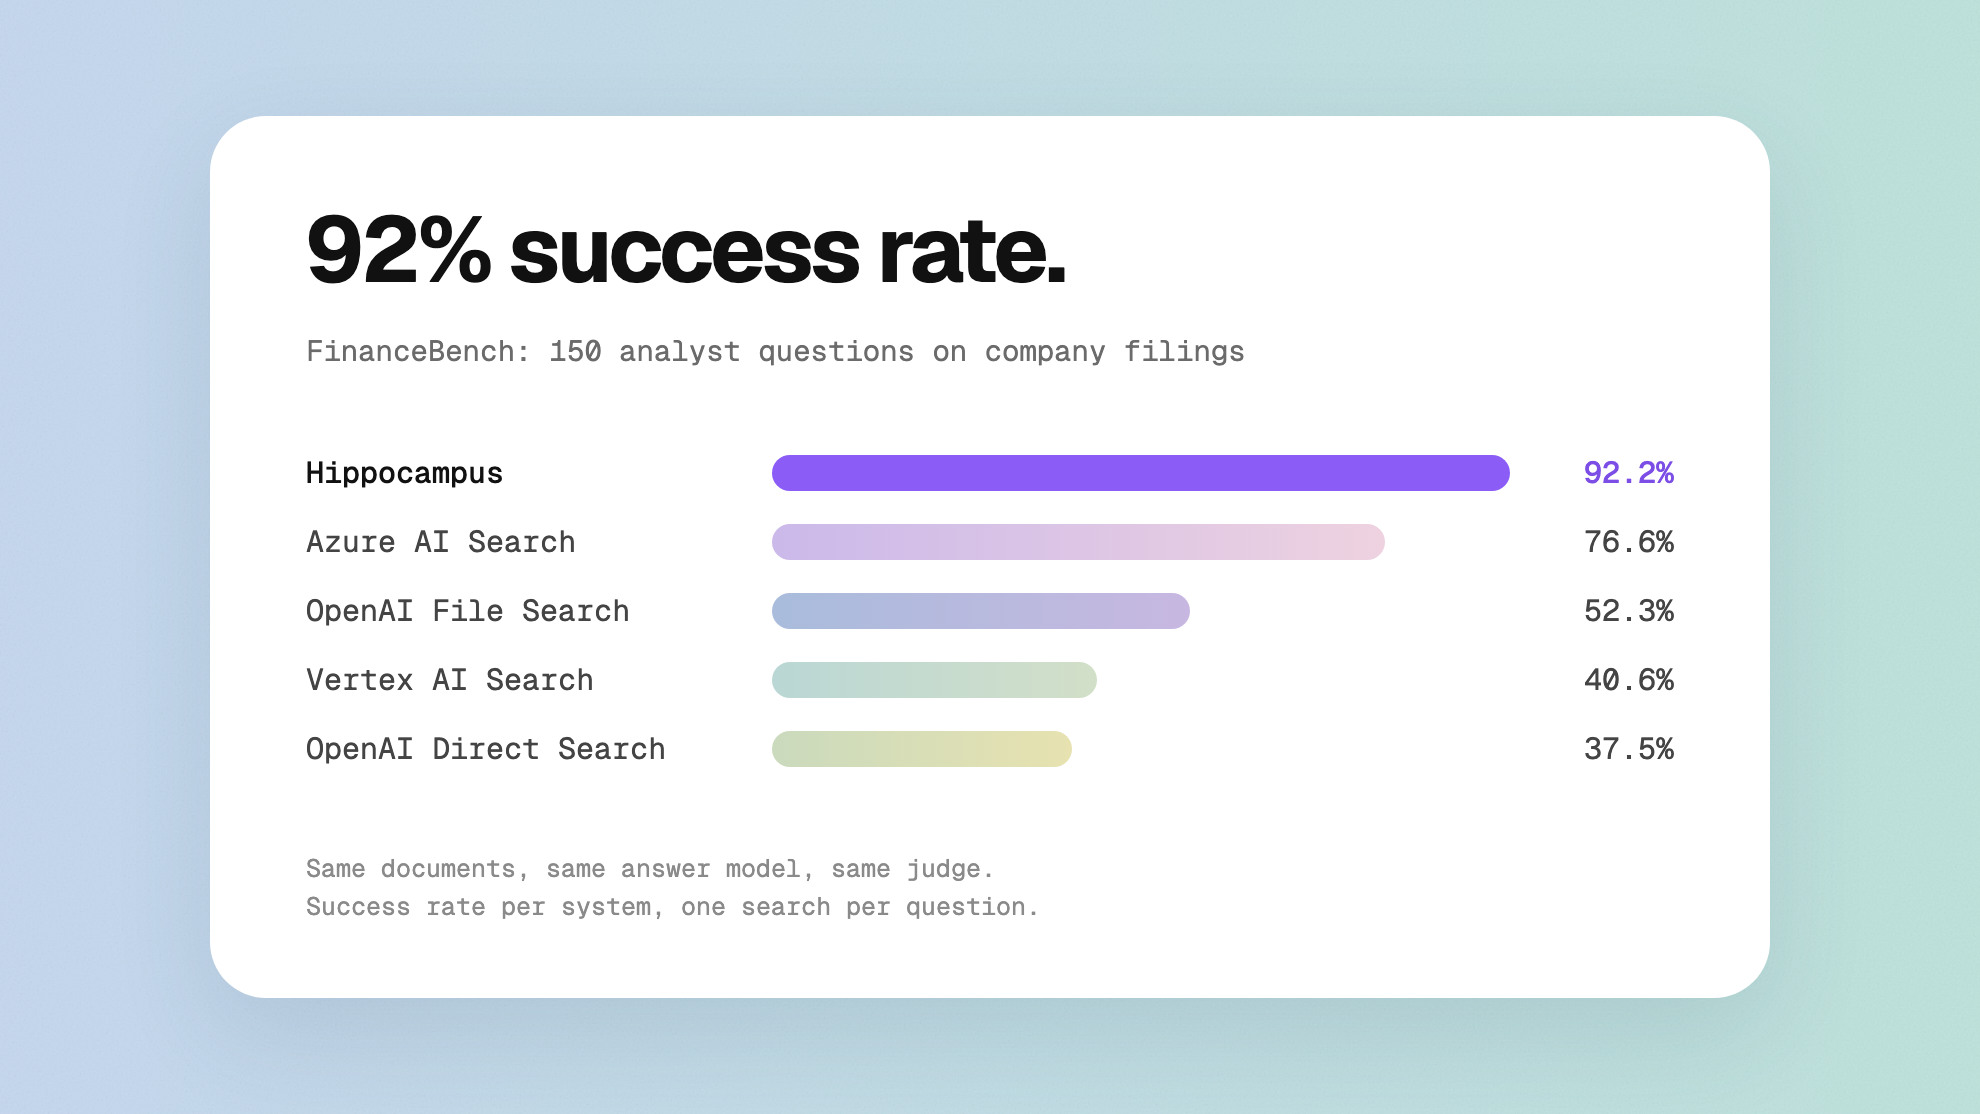
- Success rate: of the questions a perfect search would solve, the share each system solves. A perfect search here is the answer model handed each question's own evidence pages; the questions it still misses (a wrong reference answer, an ambiguous question, or one too hard even with the right pages) are left out.
- Answered right (all questions): every question counts, nothing filtered out. An answer is right when the judge finds it in line with the dataset's reference answer. Hippocampus 86%, Azure AI Search 70%.
- Evidence found: the share of the passages needed to answer that the search found, on average.
- For scale: with no documents, the answer model gets 40.7% right from memory. With the right pages, it gets 85.3% right.
Results
| System |
Success rate |
Answered right (all questions) |
Evidence found |
| Hippocampus |
92.2% |
86.0% |
85% |
| Azure AI Search |
76.6% |
70.0% |
58% |
| OpenAI File Search |
52.3% |
48.7% |
35% |
| Vertex AI Search |
40.6% |
37.3% |
24% |
| OpenAI Direct Search |
37.5% |
32.7% |
23% |
- Head to head against Hippocampus: Azure AI Search 29 : 5 (p < 10⁻⁴), OpenAI File Search 60 : 4 (p < 10⁻¹³), Vertex AI Search 76 : 3 (p < 10⁻¹⁸), OpenAI Direct Search 82 : 2 (p < 10⁻²¹). Each pair is the questions Hippocampus got right and the other system did not, against the reverse (two-sided sign test).
Vertex AI Search and OpenAI Direct Search score below the no-documents level: with weak search results, the model more often declines instead of guessing. Some reference answers pick one of several standard formulas or one reading of a vague question; about 7% of the questions (10 of 150) are disputed.
Our misses
An automated audit checked the 21 questions Hippocampus did not answer right: 9 real misses, 8 ambiguous questions, 4 reference problems and none right but less complete. Real misses are 6% of all questions. The audit is an aid to reading the misses, not a human verdict.
Speed
Hippocampus is the most accurate here, not the fastest. At the median, a search takes 1.8 seconds in Hippocampus, 0.4 seconds in Azure AI Search, 0.3 seconds in Vertex AI Search and 1.7 seconds in OpenAI Direct Search. These times are from version 2.4 of the report and cover the search only.
For a plain answer in one clearly distinct document, a fast cloud search is often good enough. When documents look alike, an answer needs several passages, or a mistake is costly, the extra time buys a different result.
How we tested
Every system indexed the same files and made one search per question. The same answer model (GPT-5.4 mini) and the same judge (Claude Sonnet 5) handled every answer. The full settings and prompts are on the evidence page under the Finance tab.
The dataset
FinanceBench (the open-source 150) is by Patronus AI, at github.com/patronus-ai/financebench, under the CC BY-NC 4.0 licence. We use it as published and report scores only: no question, answer or passage is reproduced here.